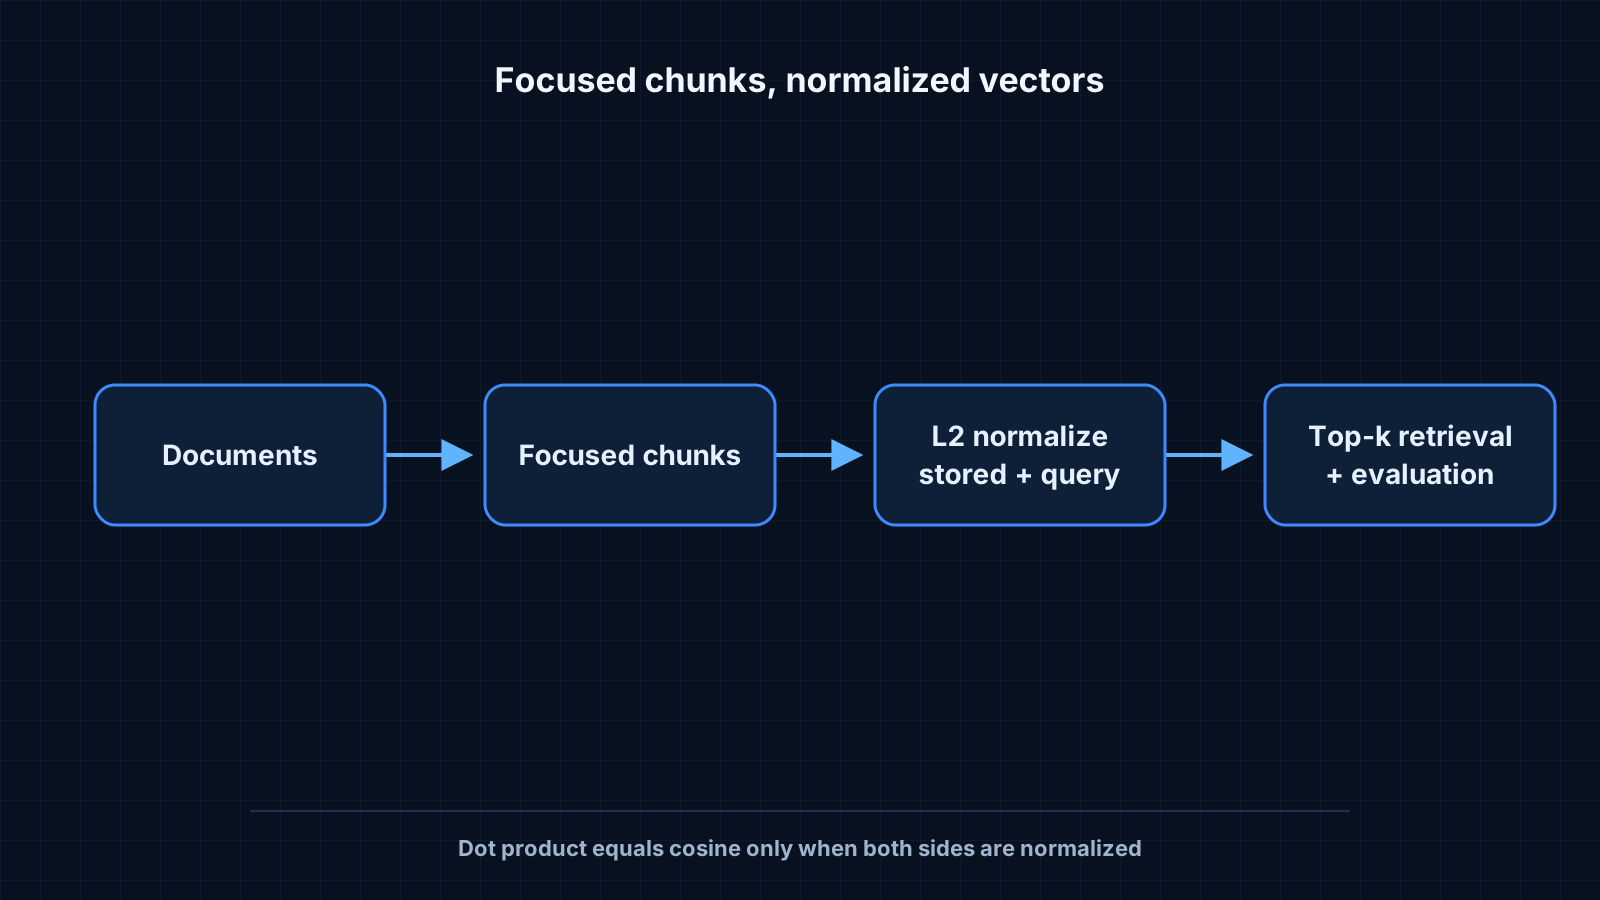
Switching embedding models moved my retrieval quality a little. Changing chunks from whole pages to a few paragraphs with a short overlap moved it a lot. Small, focused chunks match focused questions.
Cosine similarity compares directions rather than lengths. L2-normalise both the vectors you store and every query vector; the dot product between two normalised vectors is then equal to their cosine similarity.
import numpy as np

def normalise(vector: np.ndarray) -> np.ndarray:
    norm = np.linalg.norm(vector)
    if norm == 0:
        raise ValueError("cannot normalise a zero vector")
return vector / normWhen a RAG answer is wrong, first check whether the right chunk was retrieved at all. Keep a small list of questions with the chunk that should answer them, and measure how often it appears in the top results.
Key takeaway
If retrieval is wrong, no prompt will fix the answer.
- scikit-learn cosine similarity — cosine similarity as a normalized dot product.